Spreadsheet glue is still the default ops stack: download a PDF, retype four fields, paste into Sheets, hope the next person uses the same column names. It works until volume spikes or a month-end close exposes three weeks of silent typos.
Parsedit replaces that glue with a parser: same fields every time, review beside the file, then delivery to Google Sheets, QuickBooks, Xero, Zapier, webhooks, or CSV/JSON. Below are the workflows teams usually ship first, with the failure modes that matter.
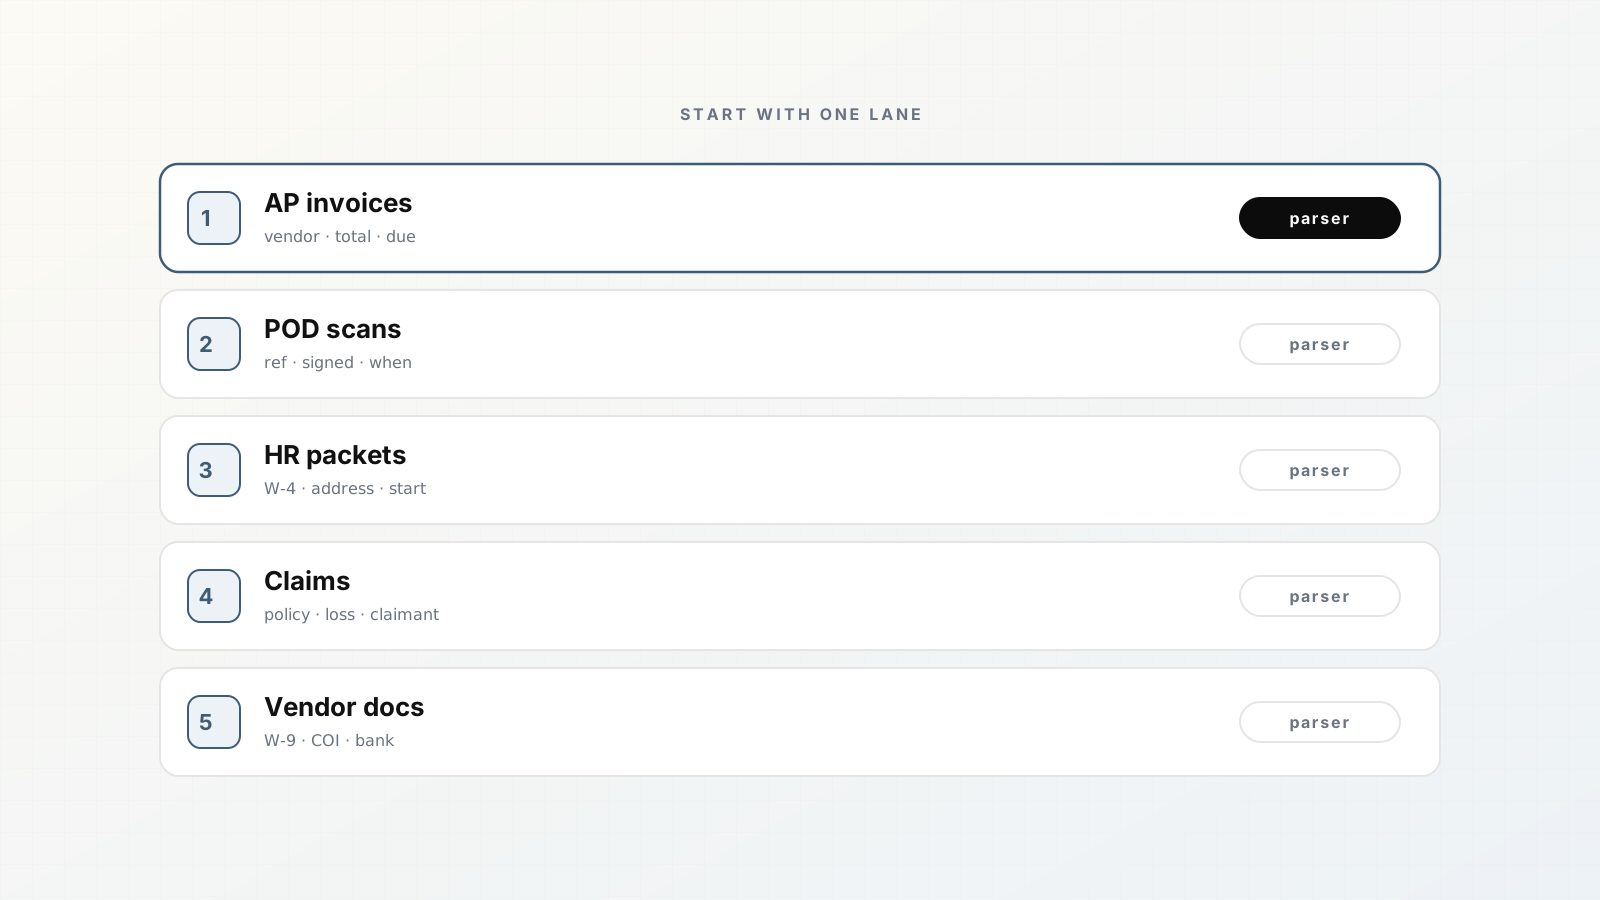
 Ship one workflow lane at a time.
Accounts payable intake
Problem. Vendors email PDF invoices (sometimes three documents in one attachment). AP retypes vendor, number, dates, totals, and maybe line items into a tracker or straight into the ledger.
Pipeline. Dedicated Invoices parser with email forwarding or a Gmail Zap into Upload Document. Extract vendor, invoice number, dates, currency, totals, and line items. Review exceptions. Send approved rows to a Sheets AP tracker, or create QuickBooks/Xero bills with the source PDF attached when allowed.
Pitfalls. Duplicate forwards, mismatched vendor names creating extra contacts, mixed invoice+PO packets. Keep auto-send off until duplicate rules and vendor matching look sane.
Related: Invoice data extraction for accounts payable, Send parsed invoices to Google Sheets, QuickBooks and Xero.
Logistics proof of delivery
Problem. Drivers upload phone photos of signed PODs. Ops stores images in Drive and answers “was it delivered?” by opening files one by one.
Pipeline. POD-oriented parser fields: shipment or reference number, delivery datetime, recipient name, address, exception notes. Intake via mobile email forward, Drive import, or Zapier from your TMS folder. Review blurry captures; OCR runs on photos automatically. Export structured rows to Sheets or a webhook your TMS already accepts.
Pitfalls. Glare, cropped signatures, multi-stop packets in one PDF. Packet splitting helps when a single upload contains several stops. See Extract proof-of-delivery data from scans and photos.
HR and onboarding packets
Problem. New hires submit mixed PDFs: tax forms, direct deposit, handbook acknowledgements. HRIS entry waits on someone to normalize names and IDs.
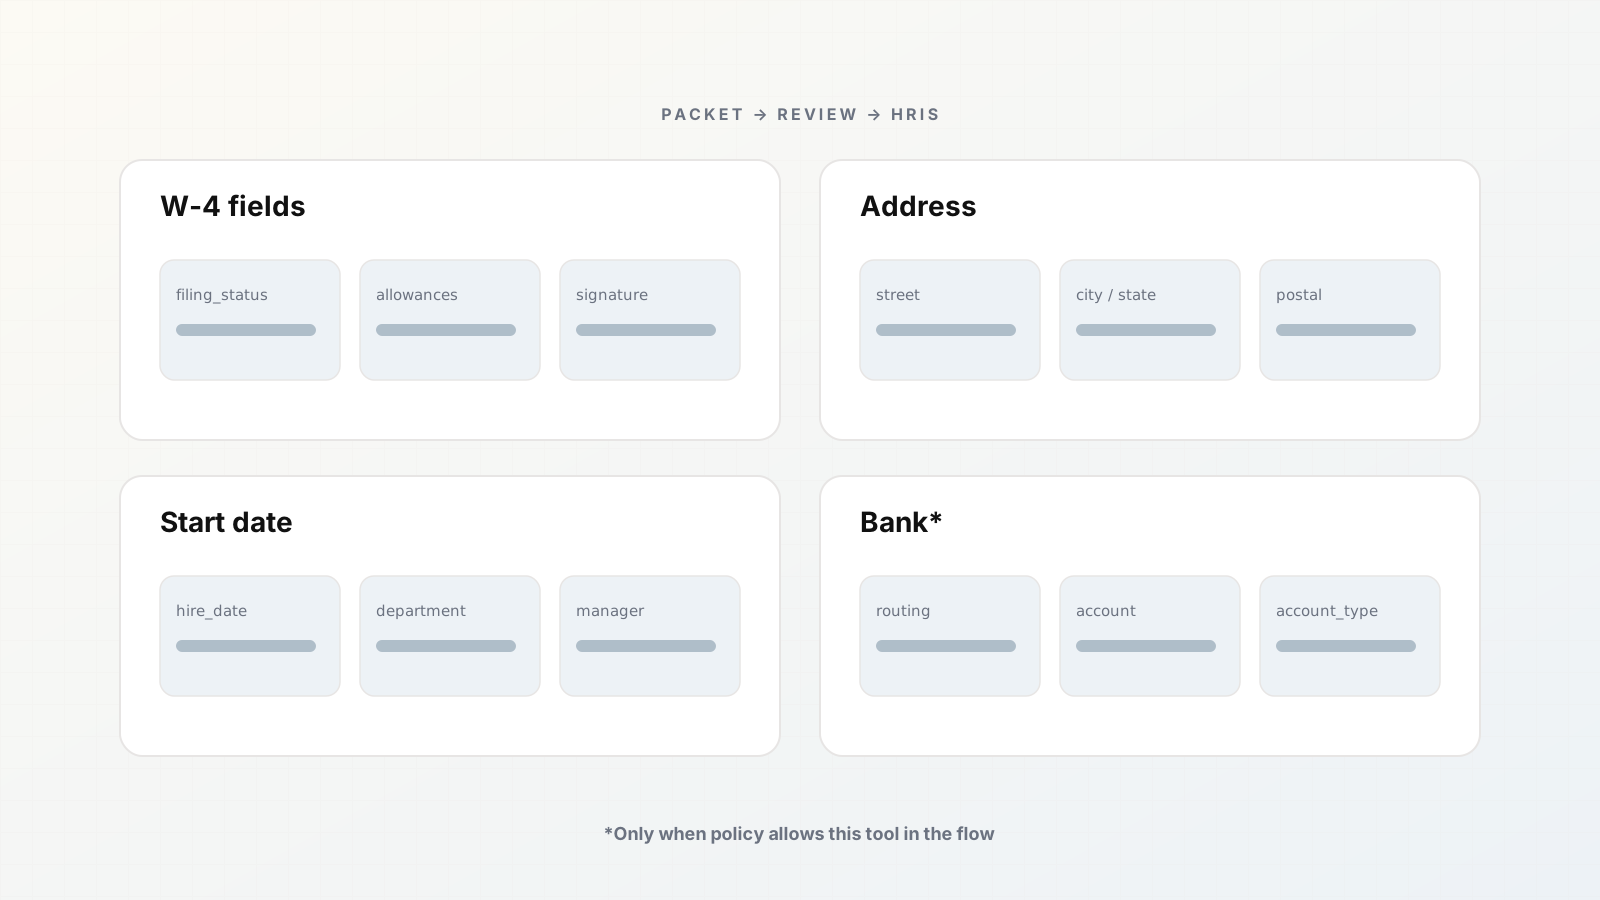
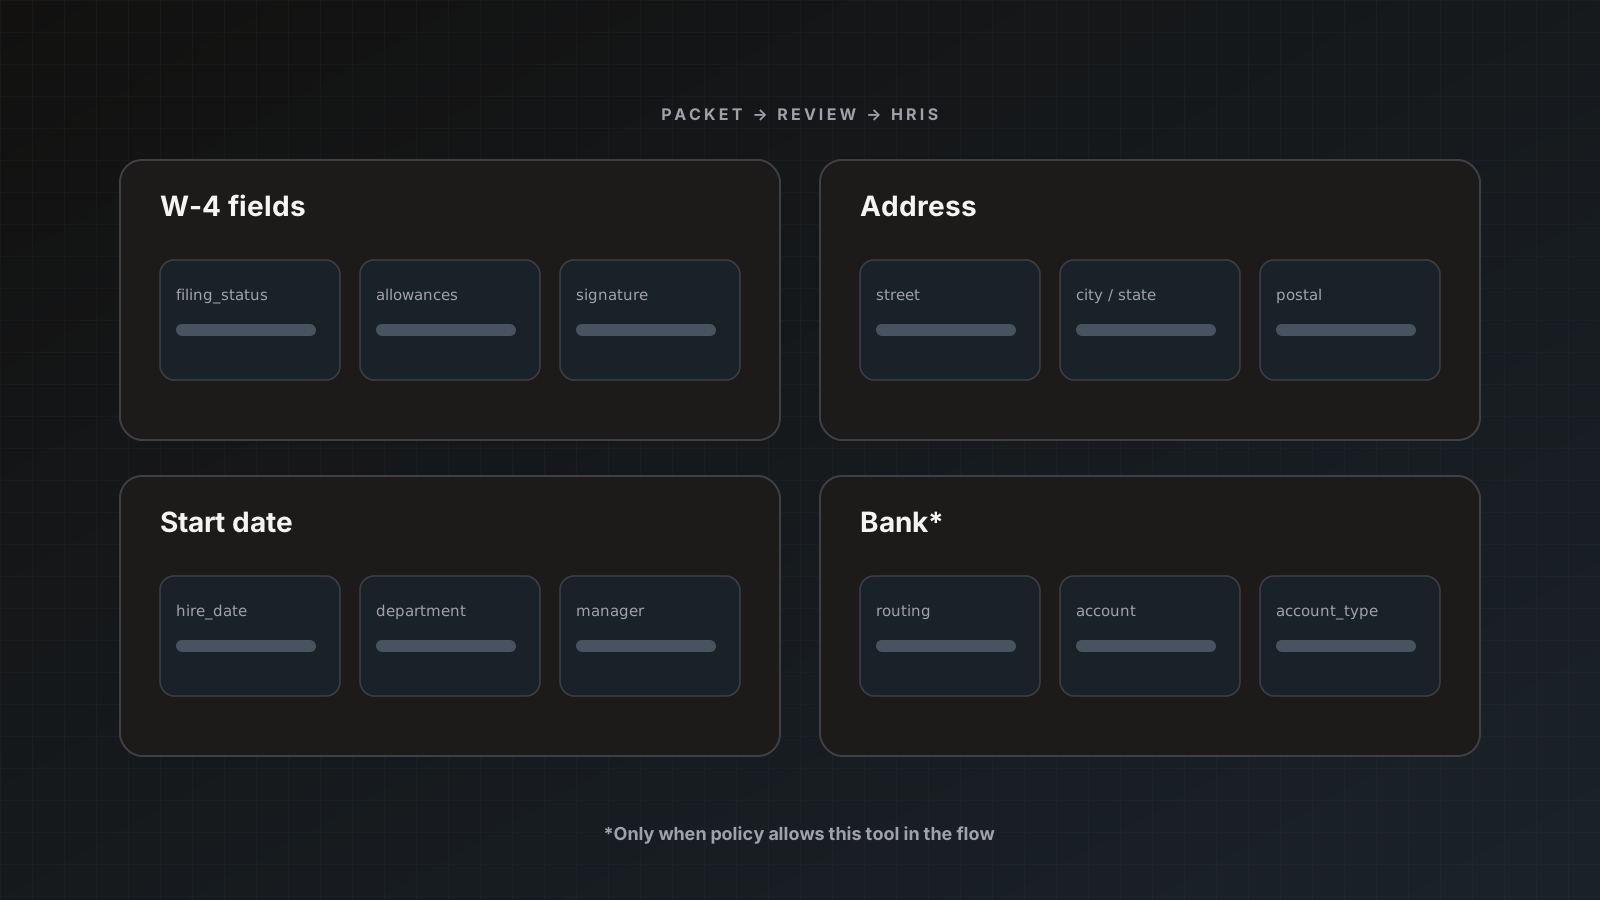
Pipeline. Parser (or separate parsers) for the forms you actually key in: W-4/W-9 style fields where relevant, addresses, bank details you are allowed to process, start dates. Review before anything hits HRIS. CSV/JSON export or Zapier into your HR tool is usually enough on day one.
Pitfalls. PII handling and least-privilege seats. Use Restricted roles so contractors only see assigned parsers. Never put live employee data in public blog screenshots; keep review inside the product.
More: Extract HR onboarding forms into a reviewable table, Data security.
Insurance FNOL and claims packets
Problem. First-notice-of-loss packs vary by carrier and channel. Adjusters dig for policy numbers, loss dates, and claimant details across scans.
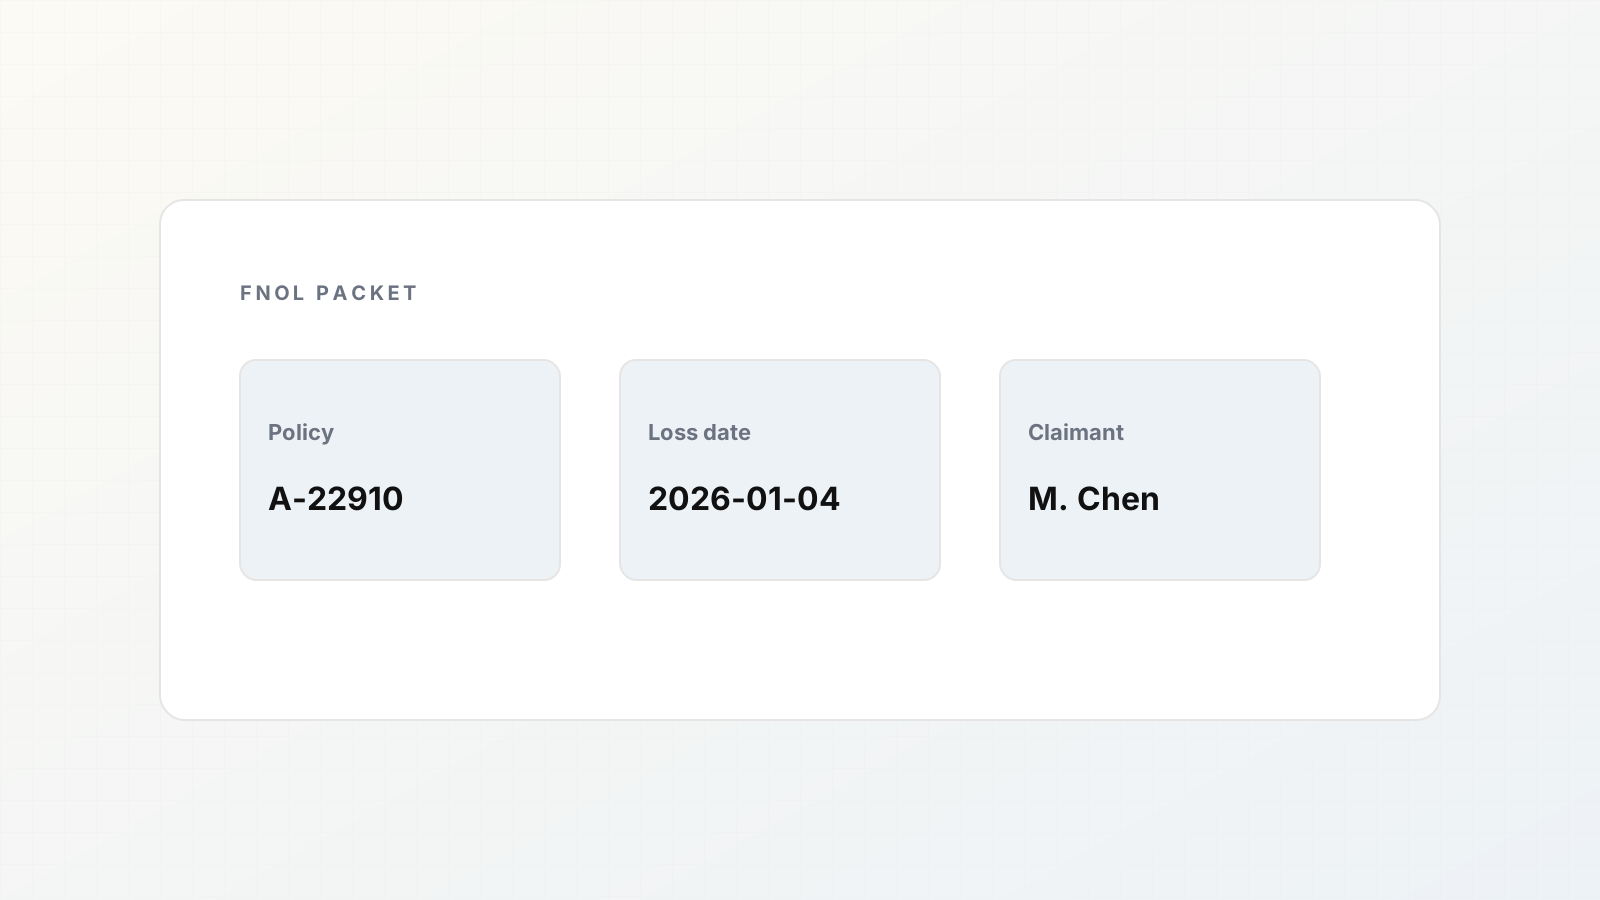
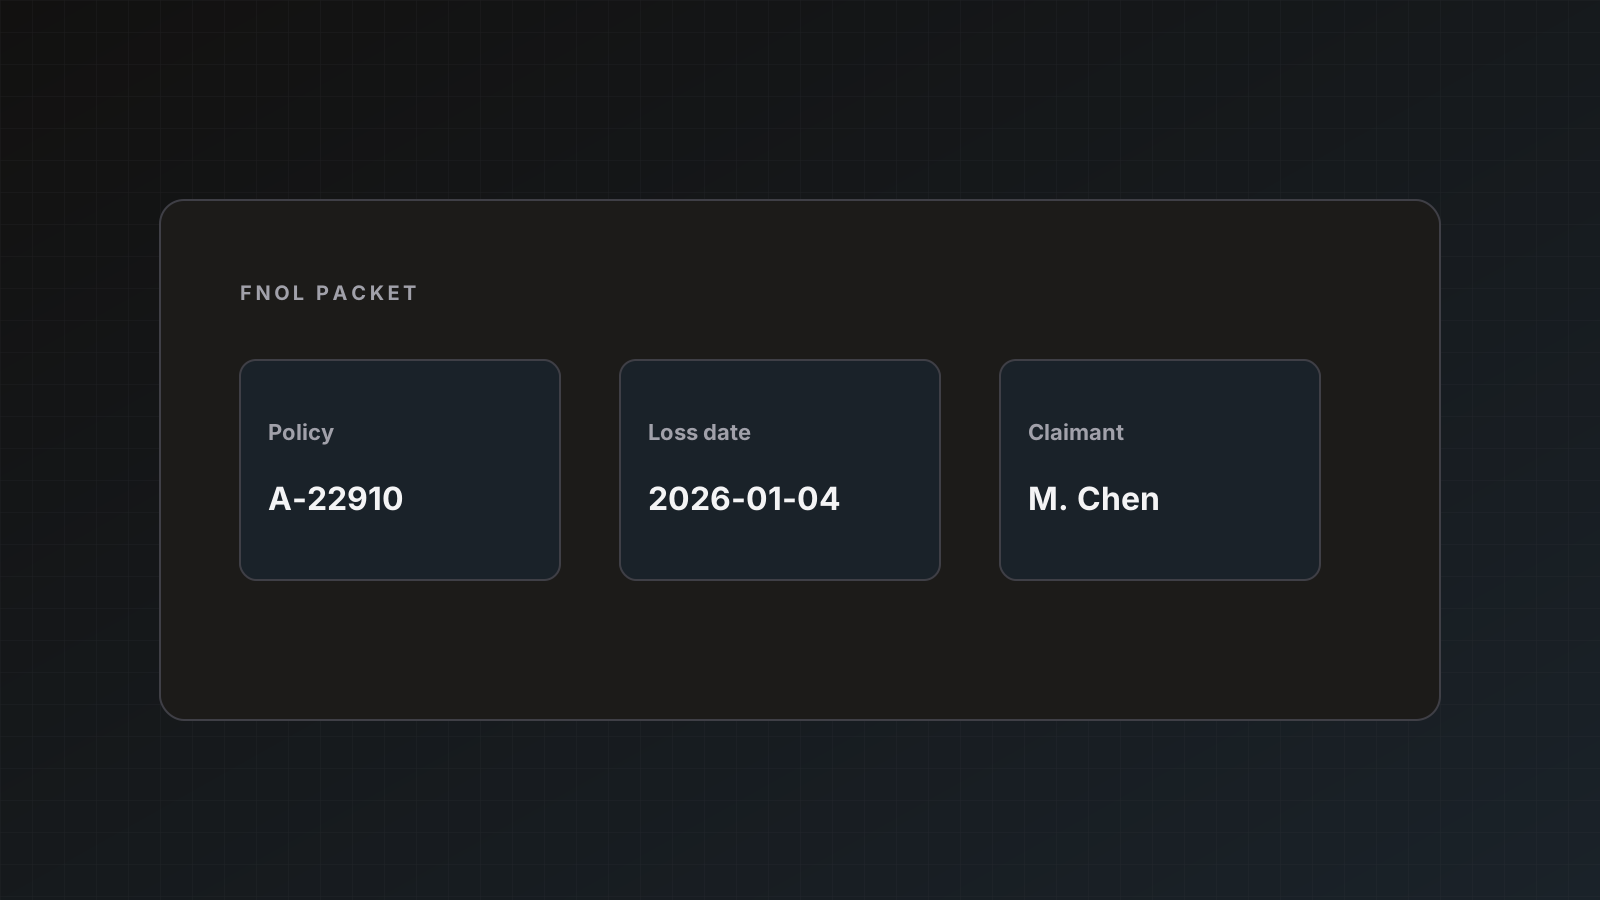
Pipeline. Template-specific parsers per major packet type. Extract policy number, incident date, claimant, location, narrative summary fields you actually use. Split mixed packets so the police report and estimate are separate children. Review, then webhook or Sheets for the claims system of record.
Pitfalls. Handwriting, low-quality faxes, 40-page dumps that burn page credits fast. Forecast volume from pages, not file counts. See Process insurance claims packets without retyping and Document packets.
Vendor onboarding
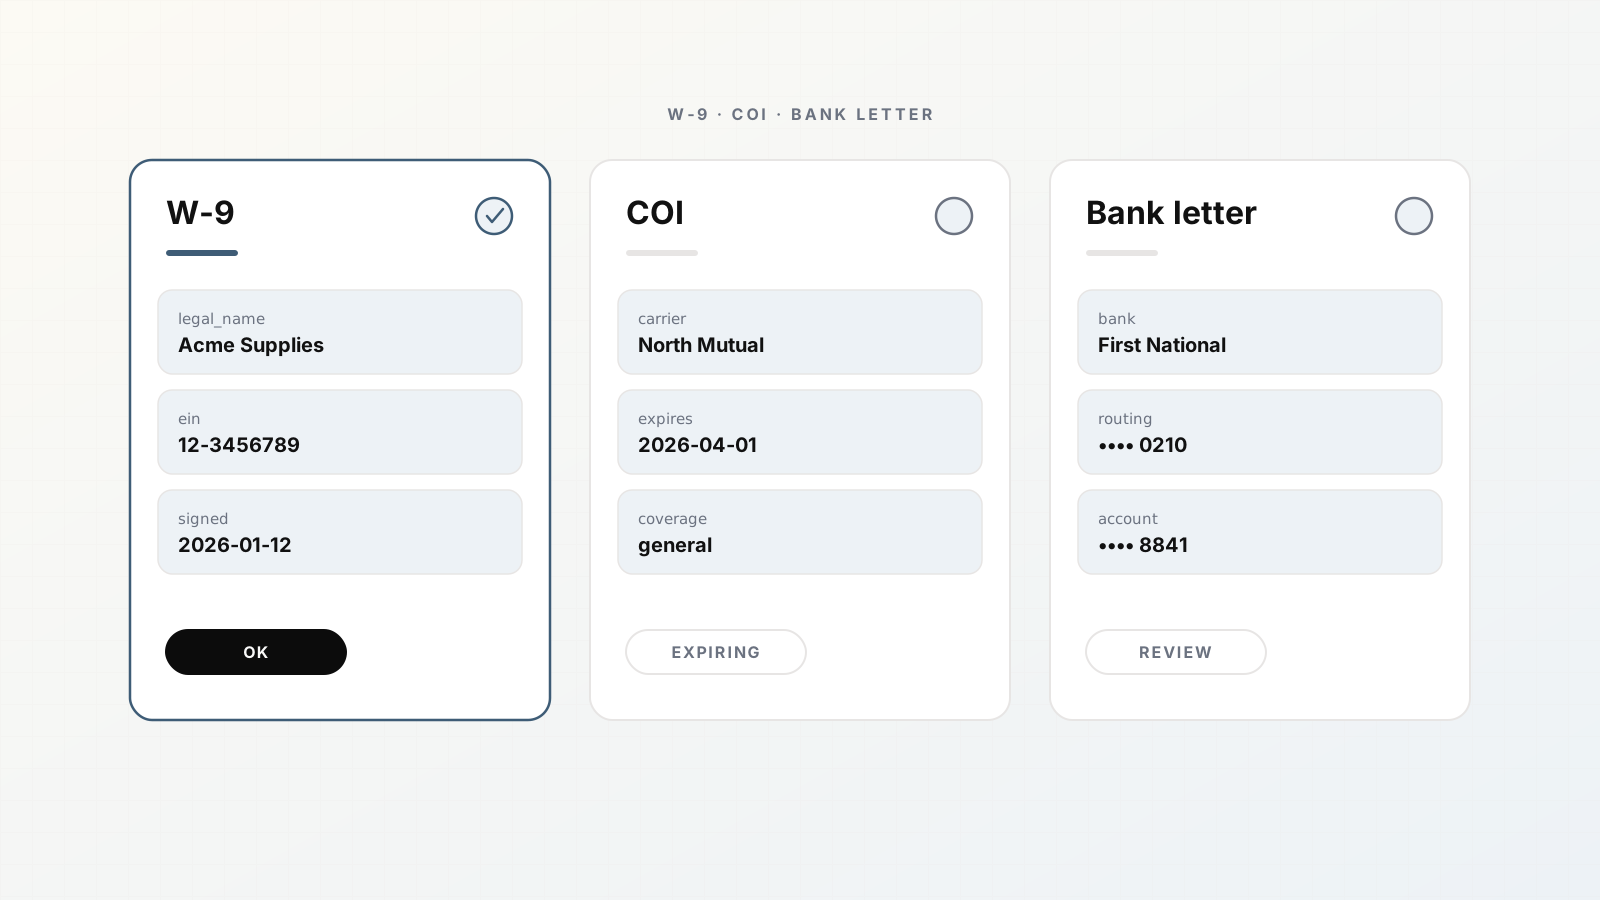
Problem. Procurement waits on W-9s, certificates of insurance, and bank letters. Missing fields surface after someone already activated the vendor.
Pipeline. Parsers for W-9 / tax forms, COI fields (insured name, coverage dates, limits), and bank letter basics. Flag empties in review before activation. Send a checklist row to Sheets or Airtable (when enabled) that procurement already uses.
Pitfalls. Expired COIs, name mismatches vs legal entity, and treating onboarding as one mega-PDF without splitting. Guide: Vendor onboarding documents.
Adjacent finance workflows worth cloning
Once AP intake is stable, the same rhythm covers:
- Remittance advice and payment processor payouts
- Purchase orders vs invoice three-way match staging in Sheets
- Bank or card statements into reviewable tables (watch page counts)
- Delivery notes / packing lists / freight invoices for ops+finance shared views
Template library coverage is listed under Document templates.
How to pick your first workflow
Score candidates on three axes:
- Frequency (weekly volume you can feel)
- Structure (fields you can name without a research project)
- Cost of error (wrong total vs wrong nickname)
Ship the document type your team already complains about. Run two weeks with review on. Automate intake second. Auto-send to the ledger last.
Setup pattern: How to build a document extraction pipeline in an afternoon. Evaluation lens: Five features operations teams need from document AI.
Where Parsedit fits
Parsedit does not replace your ERP or TMS. It turns files into approved rows and posts them where those systems already live. Soft CTA on purpose: one parser, real samples, human checkpoint.
Sequencing multiple use cases
Do not launch AP, PODs, and HR parsers the same week. Sequence by pain and shared infrastructure:
- AP invoices (clearest ROI, finance destinations ready)
- One ops POD lane
- Vendor onboarding forms
- HR forms with tighter access controls
Each reuse intake lessons without stacking failure modes.
Prioritize workflows by copy-paste hours
Rank candidates by hours spent retyping per week, then by cost of a wrong field. Automate the top of that list first. Broad “AI for documents” programs stall when every department is day one.
FAQ
Can one parser handle every use case above? You can try; you will regret it. Separate parsers keep schemas and destinations clear. Packets can still land under the parser that received the upload, with children reviewed apart.
Do we need Zapier? No. Email forwarding, Drive, upload, Sheets, QuickBooks, Xero, webhooks, and the API cover many stacks. Zapier helps when the file already lives in Gmail/Drive automation.
How do credits work across use cases? Pages, not files. A 20-page claims PDF costs 20 credits whether you care about three fields or thirty. Model this in forecast page credits.
What about handwritten forms? OCR runs on images and scans. Expect more review time. Design schemas around the fields reviewers can verify quickly.
Pick the workflow that already burns an hour a day. Create a parser and replace the copy-paste loop first.